
Ready to run the code? See the quick start: prepare data → train → evaluate.
Code and reproduction resources
- Complete code: datawhalechina/agentic-rl-lab/experiments/search-r1
- SwanLab, current official DeepSeek Search run: 30-step training record
- SwanLab, legacy DeepSeek Evidence run: historical 20-step record
- Paper: Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning
- Official DeepSeek Search API: web search and fetch guide
- PyTRIO Skill: SwanHubX/pytrio-skill
This is the third chapter in my series reproducing ten reinforcement learning algorithms.
The earlier chapters cover:
This time I finally tried an Agentic RL problem I had wanted to explore: learning when to search, what query to write, whether to search again after reading results, and when to give a final answer.
2026-10-20 update: two search backends remain. The default
--search-backend deepseekcalls the official DeepSeek Search API directly and prefers shortsnippetexcerpts. Use--search-backend wikipediafor key-free English Wikipedia search.
EM means Exact Match. Evaluation extracts the final Answer:, lowercases it, removes punctuation and English articles, and normalizes whitespace before comparing against any reference answer. An exact match scores 1; otherwise it scores 0. Keyword overlap receives no partial credit.
Macro EM first calculates EM for each of 7 benchmarks, then averages them equally so a larger dataset cannot dominate. This fixed evaluation contains 10 questions per benchmark, so Macro EM also equals overall accuracy across the 70 questions.
After integrating the official DeepSeek Search API, I evaluated Base and the 30-step checkpoint on the same fixed 70 questions. Both use the top 3 snippet excerpts with identical search backend, concurrency and timeout settings:
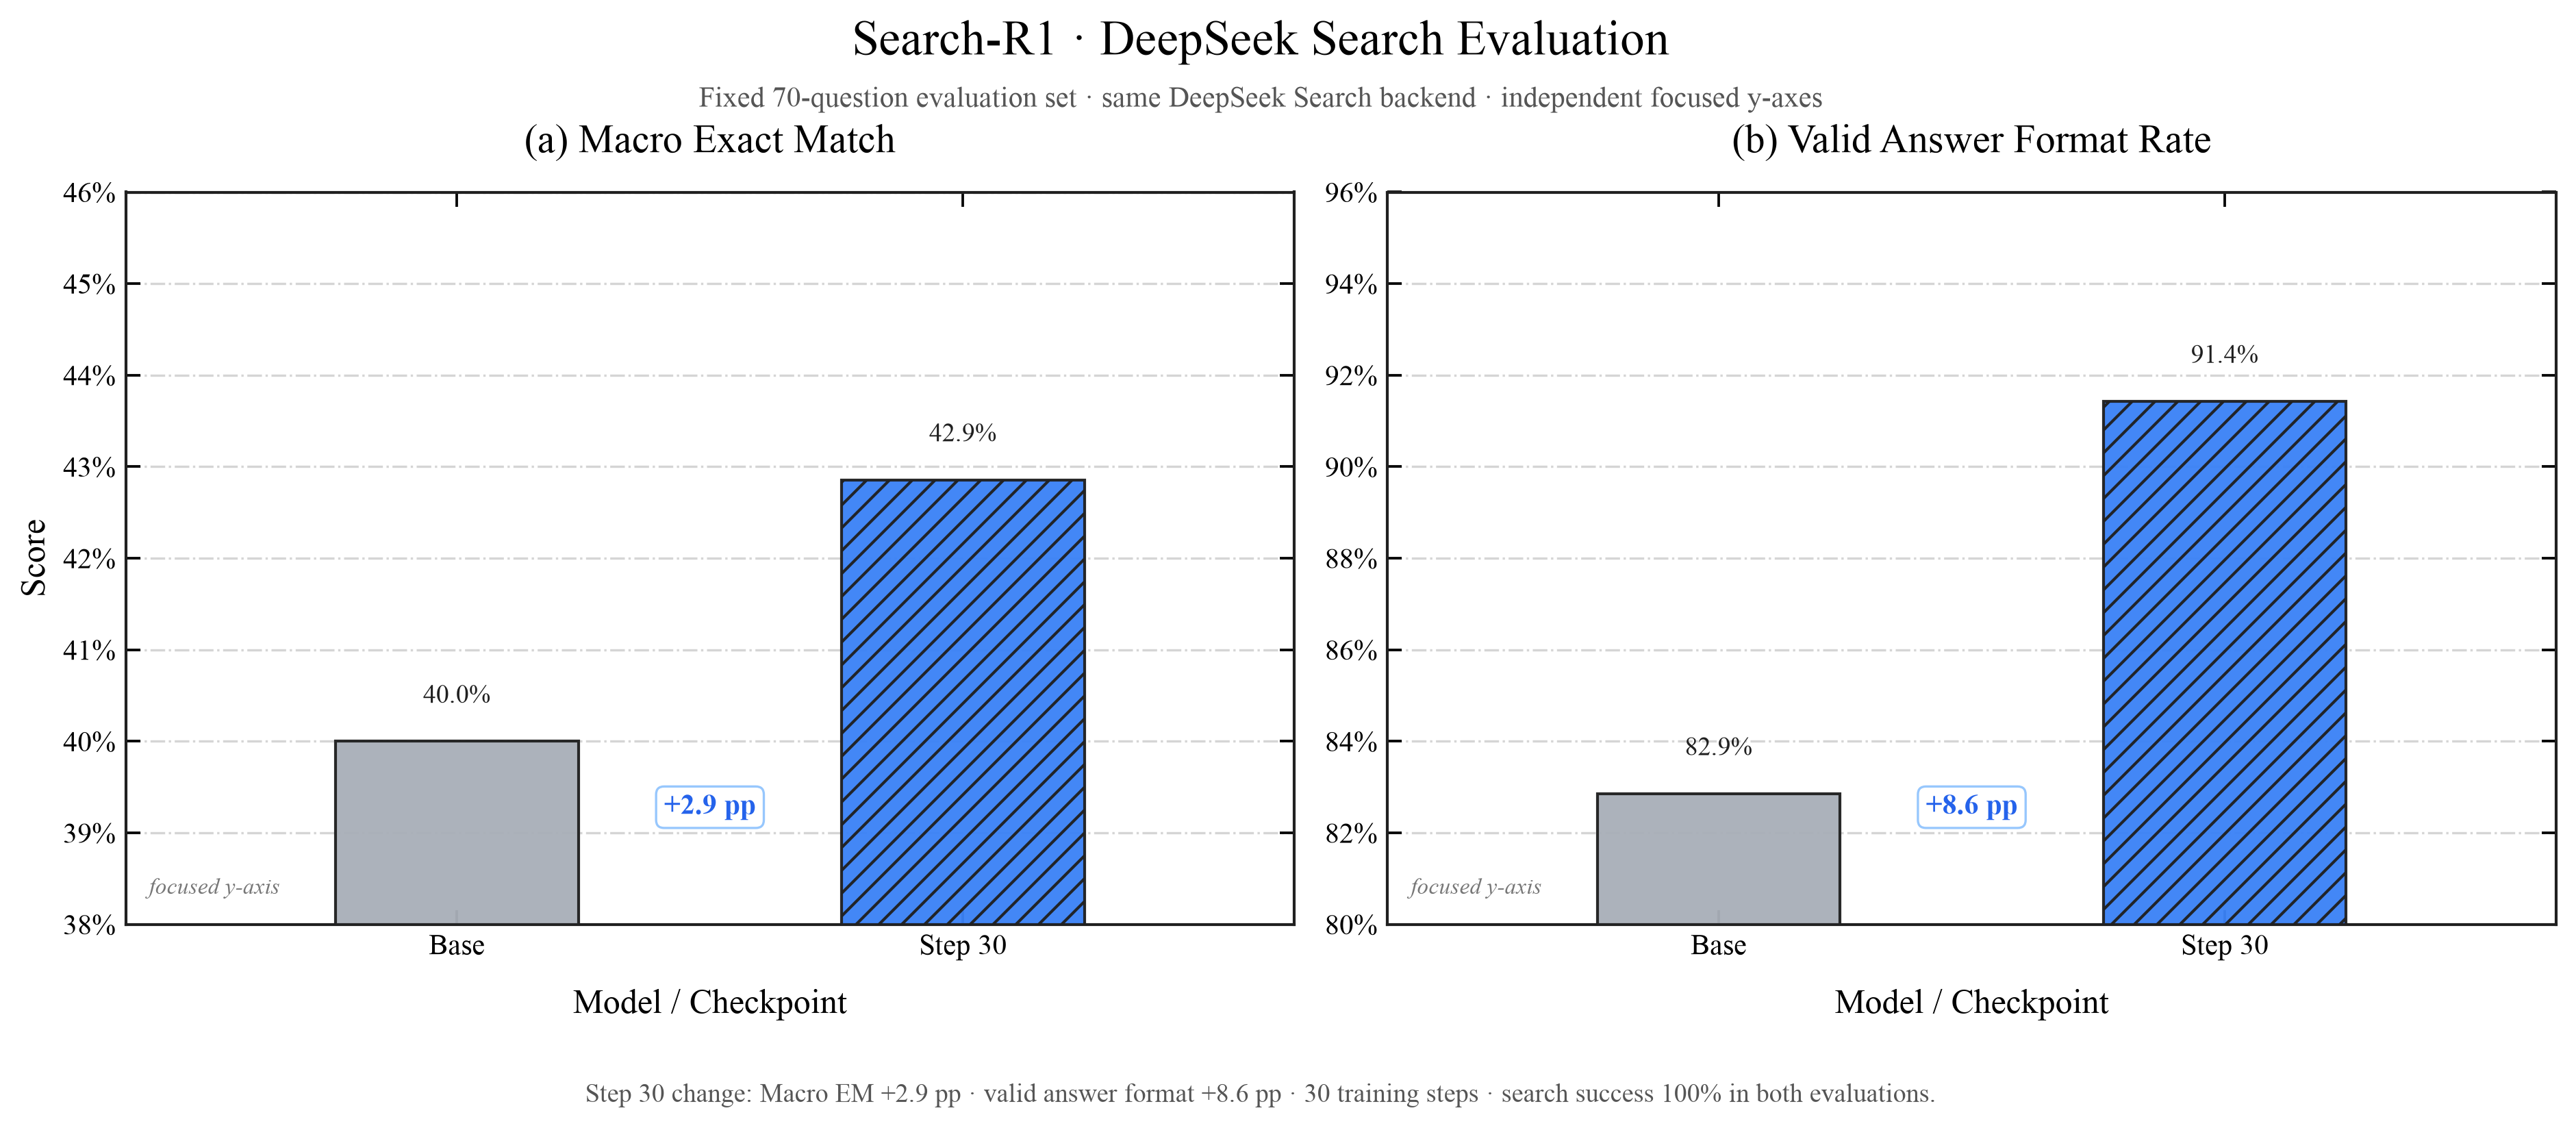
| DeepSeek Search | Macro EM | Format | Search success |
|---|---|---|---|
| Base Model | 40.00% | 82.86% | 100% |
| RL Step 30 | 42.86% | 91.43% | 100% |
| Change | +2.86 pp | +8.57 pp | — |
Step 30 answers 2 more questions correctly and produces 6 more validly formatted answers than Base. Both evaluations have 100% search success, with no timeouts or 429 responses. These results come from one training run and 70 questions: both EM and Format improve in this evaluation, while larger evaluations and repeated runs are needed to establish stability.
The goal is to make Search-R1's algorithm accessible to ordinary developers. Qwen3.5-4B, PyTRIO and switchable online search provide a runnable loop without first deploying the original retrieval and training infrastructure.
Where does Search-R1 come from?
Search-R1 was introduced by Bowen Jin and colleagues in 2025, titled:
Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning
Its motivation is practical.
Traditional RAG commonly retrieves once before answering:
问题 → 检索 → 把结果塞进 prompt → 模型回答That works for simple factual questions, but multi-hop questions often need several searches. For example:
《小王子》的作者出生在哪个国家?The model may first search:
The Little Prince authorAfter identifying Antoine de Saint-Exupéry as the author, it searches:
Antoine de Saint-Exupéry birthplace countryIt can then answer France.
A working search engine is only the beginning. The model must decide:
- Is the current evidence sufficient?
- What should the next query be?
- Which entity in the results is the next hop?
- Should it keep searching or stop and answer?
Prompt instructions can guide these choices at inference. Search-R1 instead uses reinforcement learning to train the pattern of alternating reasoning and search into model parameters.
The central change is:
Search becomes an action the model can repeatedly choose throughout reasoning.
Search-R1 in everyday terms
Imagine a student taking an open-book exam.
In ordinary RAG, the teacher retrieves a page of material first and then asks the student to answer.
Search-R1 gives the student a search box. The student can think, submit a query, read results, revise the query when information is insufficient, and answer when the evidence seems adequate.
At the end, grading checks the answer:
- Correct answers receive higher reward.
- Incorrect answers receive lower reward.
- Missing the required answer format incurs a small additional penalty.
Several trajectories for the same question are compared. Those above the group mean are encouraged; those below it are discouraged.
The complete process is:
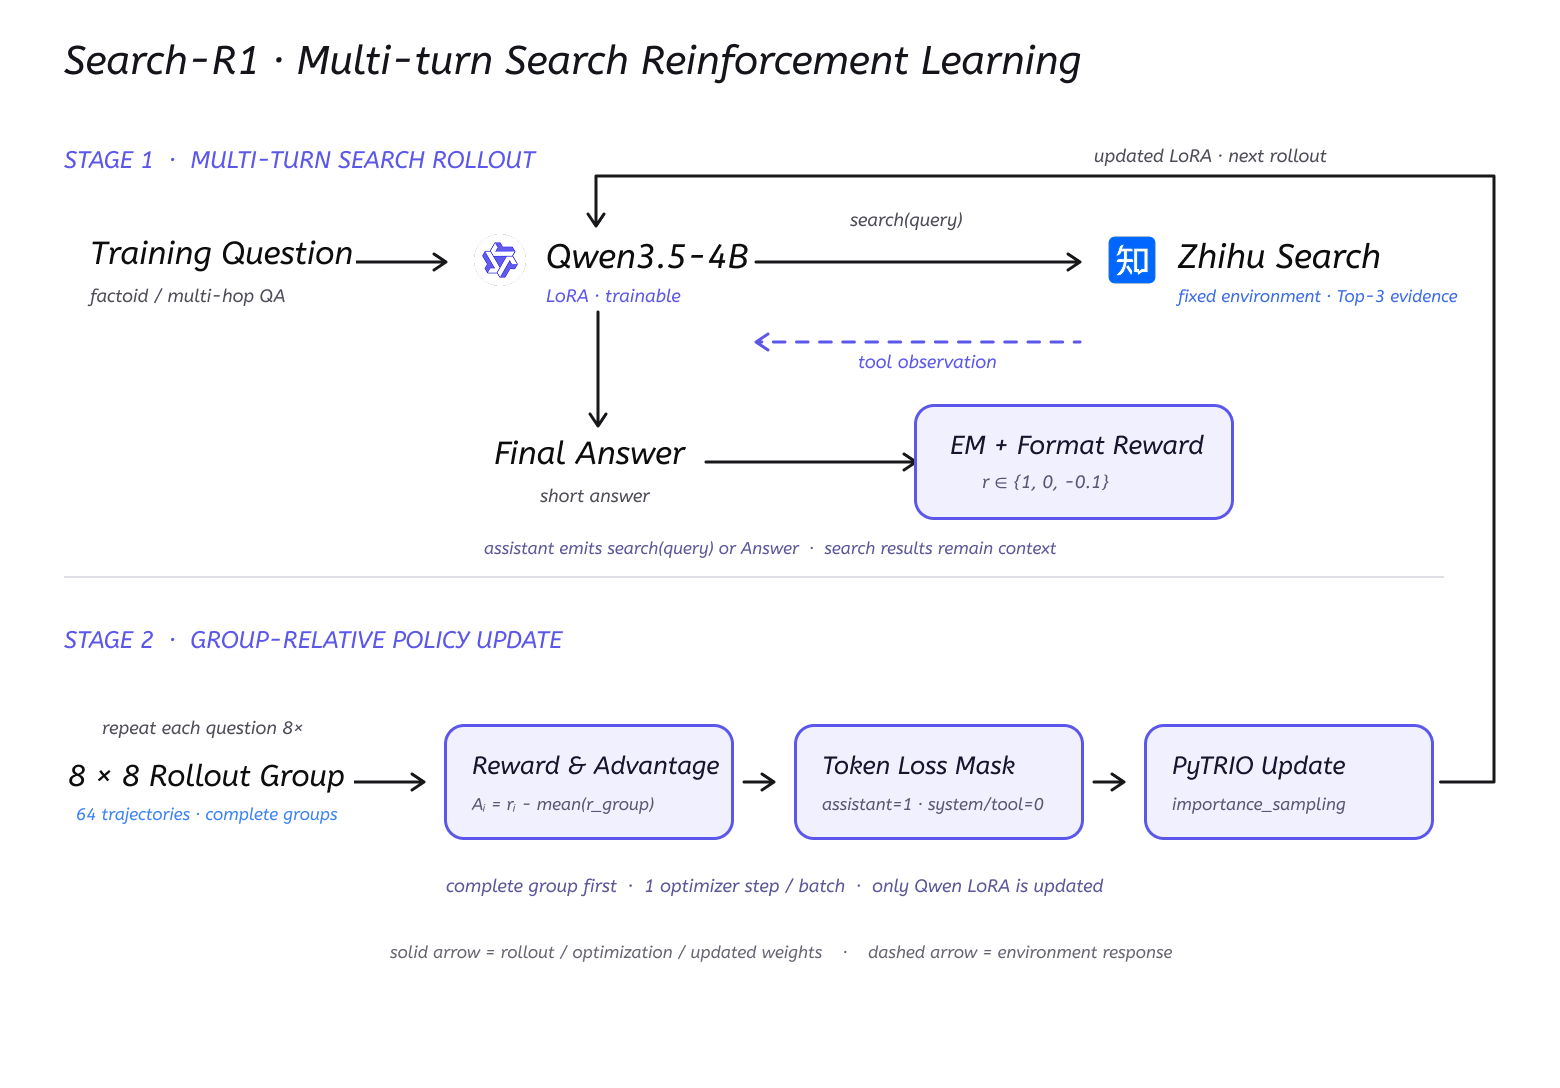
One distinction matters:
Training updates the language model's LoRA weights. The search engine and embedding model remain fixed parts of the environment.
The model learns when to call search, how to form queries, how to use returned evidence and when to stop.
How did we reproduce it?
Original Search-R1 builds on veRL. Its official quick start downloads a Wikipedia corpus and E5 index, then launches a local retrieval server.
I initially followed that route. The downloaded, extracted database was about 160 GB, and a smoothly running retrieval service required roughly 180 GB of memory in that setup. Those resources can be appropriate for a close paper reproduction, but they also distract a first-time learner from the algorithm.
Before reaching rewards, advantages and loss masks, learners can encounter infrastructure work such as:
索引怎么下载?
为什么解压后磁盘不够?
Faiss 为什么启动失败?
retriever server 为什么 OOM?
训练卡和检索卡应该怎么分?
These are real engineering problems, separate from the core reward, advantage and masking mechanisms.
I replaced local retrieval with a switchable online search environment:
原论文:本地 Wikipedia corpus + E5 retriever
本文:  DeepSeek 官方 Search API(默认,使用 snippet 短摘要)
        或 Wikipedia Action API
The official code also supports replacing local retrieval with online search. The algorithm requires an interface of this form:
search(query) → observationsThe model still generates queries, reads observations, continues reasoning and receives final rewards, preserving the central training loop.
The current DeepSeek backend calls the official POST https://api.deepseek.com/v1/tools/search directly, requesting 3 results by default. Tool observations retain the title, short snippet, source and URL, falling back to summary only when snippet is missing. Requests always set need_content=false, with no additional model call to organize evidence or Fetch call to retrieve pages. The agent generates queries, judges evidence, chooses further searches and produces its final answer.
Both backends implement search(query) → observations:
| Backend | Returned content | Default concurrency | Default timeout | Cost and stability |
|---|---|---|---|---|
| Official DeepSeek Search API | Top 3 web excerpts, titles, sources and URLs | 16 | 60 seconds | 5 yuan per 1,000 billable requests |
| Wikipedia | Top 3 English article excerpts and URLs | 3 | 15 seconds | No key or search API charge; evidence limited to Wikipedia |
The Wikipedia client sends an identifiable User-Agent and bounds request starts to about 200 RPM, following the published Wikimedia API limits used for this implementation. One Action API request searches and obtains excerpts from the top 3 pages without separate page fetches.
For the official Search API, count does not change the per-request price. Only HTTP 200 responses with nonempty results are billable. The current account-level rate limit is 100 QPS. Refer to the official billing information for prices and free periods; its November 1, 2026 charging date specifically concerns server-side tool calls in Harness, Claude Code and Codex.
The historical 20-step experiment below used the legacy deepseek-search Evidence integration. Its roughly 14.06 yuan daily usage included search-model tokens and must not be treated as a cost or performance record for the official Search API.
Our configuration is:
| Item | This implementation |
|---|---|
| Base Model | Qwen/Qwen3.5-4B |
| Trainable parameters | LoRA rank 32 |
| Training framework | PyTRIO |
| Search environment | Official DeepSeek Search API / Wikipedia, selected by argument |
| Training data | NQ + HotpotQA |
| Questions per step | 8 |
| Trajectories per question | 8 |
| Maximum searches | 4 |
| Maximum assistant turns | 6 |
| Maximum trajectory length | 8,192 tokens |
| Reward | Exact Match + Format |
| Advantage | reward - group_mean |
| Loss | importance_sampling |
This is a core-algorithm reproduction. It retains questions, tools, interaction, group-relative advantages, retrieved-token masking and policy updates, while replacing the heavy local retriever. It does not reproduce every infrastructure detail or the paper's final scores.
For learning, Wikipedia offers a key-free path, while the official DeepSeek Search API offers general web coverage and higher concurrency. A closer benchmark reproduction could later restore the local Wikipedia retriever behind the same interface.
Why use PyTRIO for Agentic RL?
I had tried frameworks such as veRL before. They are capable, but studying one algorithm can first require combined training/inference setup, weight synchronization, vLLM, distributed execution and multi-GPU scheduling.
Agentic RL adds work beyond model generation within a rollout:
模型生成 → 工具调用 → 等待环境 → 模型继续生成 → 再调用工具 → ……On a rented 8-GPU server, waiting for search APIs or long-tail rollouts may leave GPUs idle while wall-clock billing continues.
The billing unit matters. A rented machine typically charges for occupied time, including training and waits. Variable tool latency and trajectory length can therefore make idle time a real cost.
In the PyTRIO setup used here, training is charged by processed training tokens. Waiting for search, local tool execution or unfinished rollouts produces no additional training tokens. Compute still has a cost, but search and scheduling waits do not keep adding to the training-token bill.
The following screenshots preserve bills and drink prices from an early experiment. The two PyTRIO sessions cost 0.44 yuan for evaluation and 13.30 yuan for training. These historical bills and prices explain the drink comparison on the original cover.
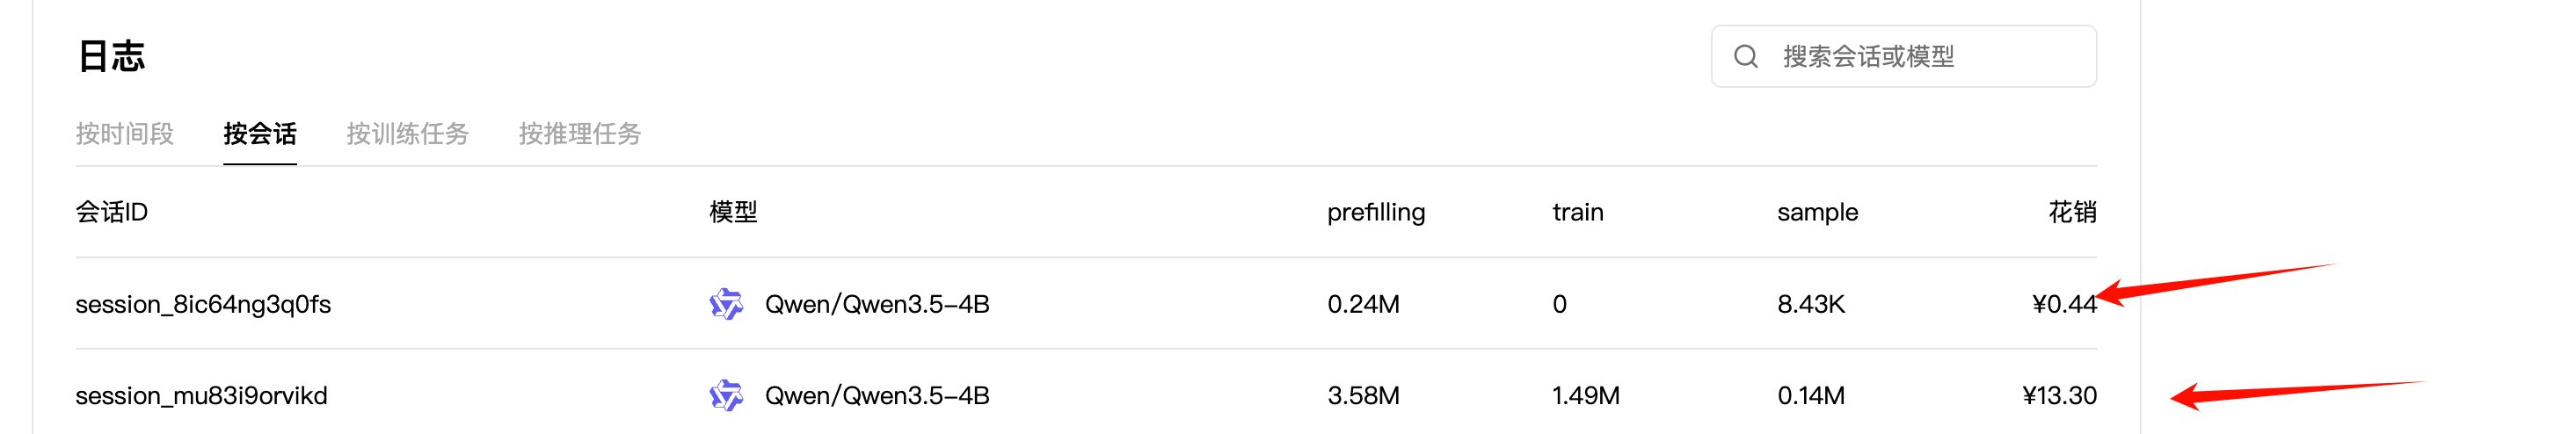
The division of work is:
- Local Python: data, tools, rollout state machine, rewards, advantages and experiment loop.
- PyTRIO: sampling, forward/backward passes, LoRA optimizer, checkpoints and sampler weights.
The local loop calls ordinary Python interfaces:
sampling_client = training_client.save_weights_and_get_sampling_client()

training_client.forward_backward(
    datums,
    loss_fn="importance_sampling",
).result()

training_client.optim_step(adam_params).result()
See the complete loop in train.py.
This keeps rollout and training responsibilities clear while using remote compute. For a task with long generation and tool interaction but relatively short backward computation, that separation is useful.
For me, it makes the training service feel like compute accessed through an API, while local code describes the algorithm and experiment.
Evaluation after 30 training steps
This run uses the official DeepSeek Search API. The fixed evaluation has 70 questions, 10 from each of 7 benchmarks. Base and Step 30 share the same questions, tool protocol, top 3 snippet excerpts and search settings.
| Model / Checkpoint | Macro EM | Format | 2Wiki | Bamboogle | HotpotQA | MuSiQue | NQ | PopQA | TriviaQA |
|---|---|---|---|---|---|---|---|---|---|
| Qwen3.5-4B | 40.00% | 82.86% | 50% | 70% | 70% | 10% | 20% | 10% | 50% |
| RL Step 30 | 42.86% | 91.43% | 40% | 60% | 70% | 10% | 30% | 30% | 60% |
Macro EM rises from 40.00% to 42.86%, or from 28 to 30 correct answers. Format rises from 82.86% to 91.43%, or from 58 to 64 validly formatted answers.
Both evaluations have 100% search success, with no timeouts, 429 responses or request errors. Mean search calls per question rise from 1.76 to 2.77. Training changes search and answer behavior and improves scores on this set. This remains one run on 70 development questions; larger evaluations and repeated runs are needed to establish stability.
Legacy DeepSeek Evidence: a historical 20-step experiment with stable search
We also retain a historical 20-step run using the old deepseek-search Evidence backend. Its Base and Step 20 checkpoint were evaluated on the same 70 questions within that environment, separately from the official Search API comparison above.
Training log: SwanLab, legacy DeepSeek 20-step experiment.
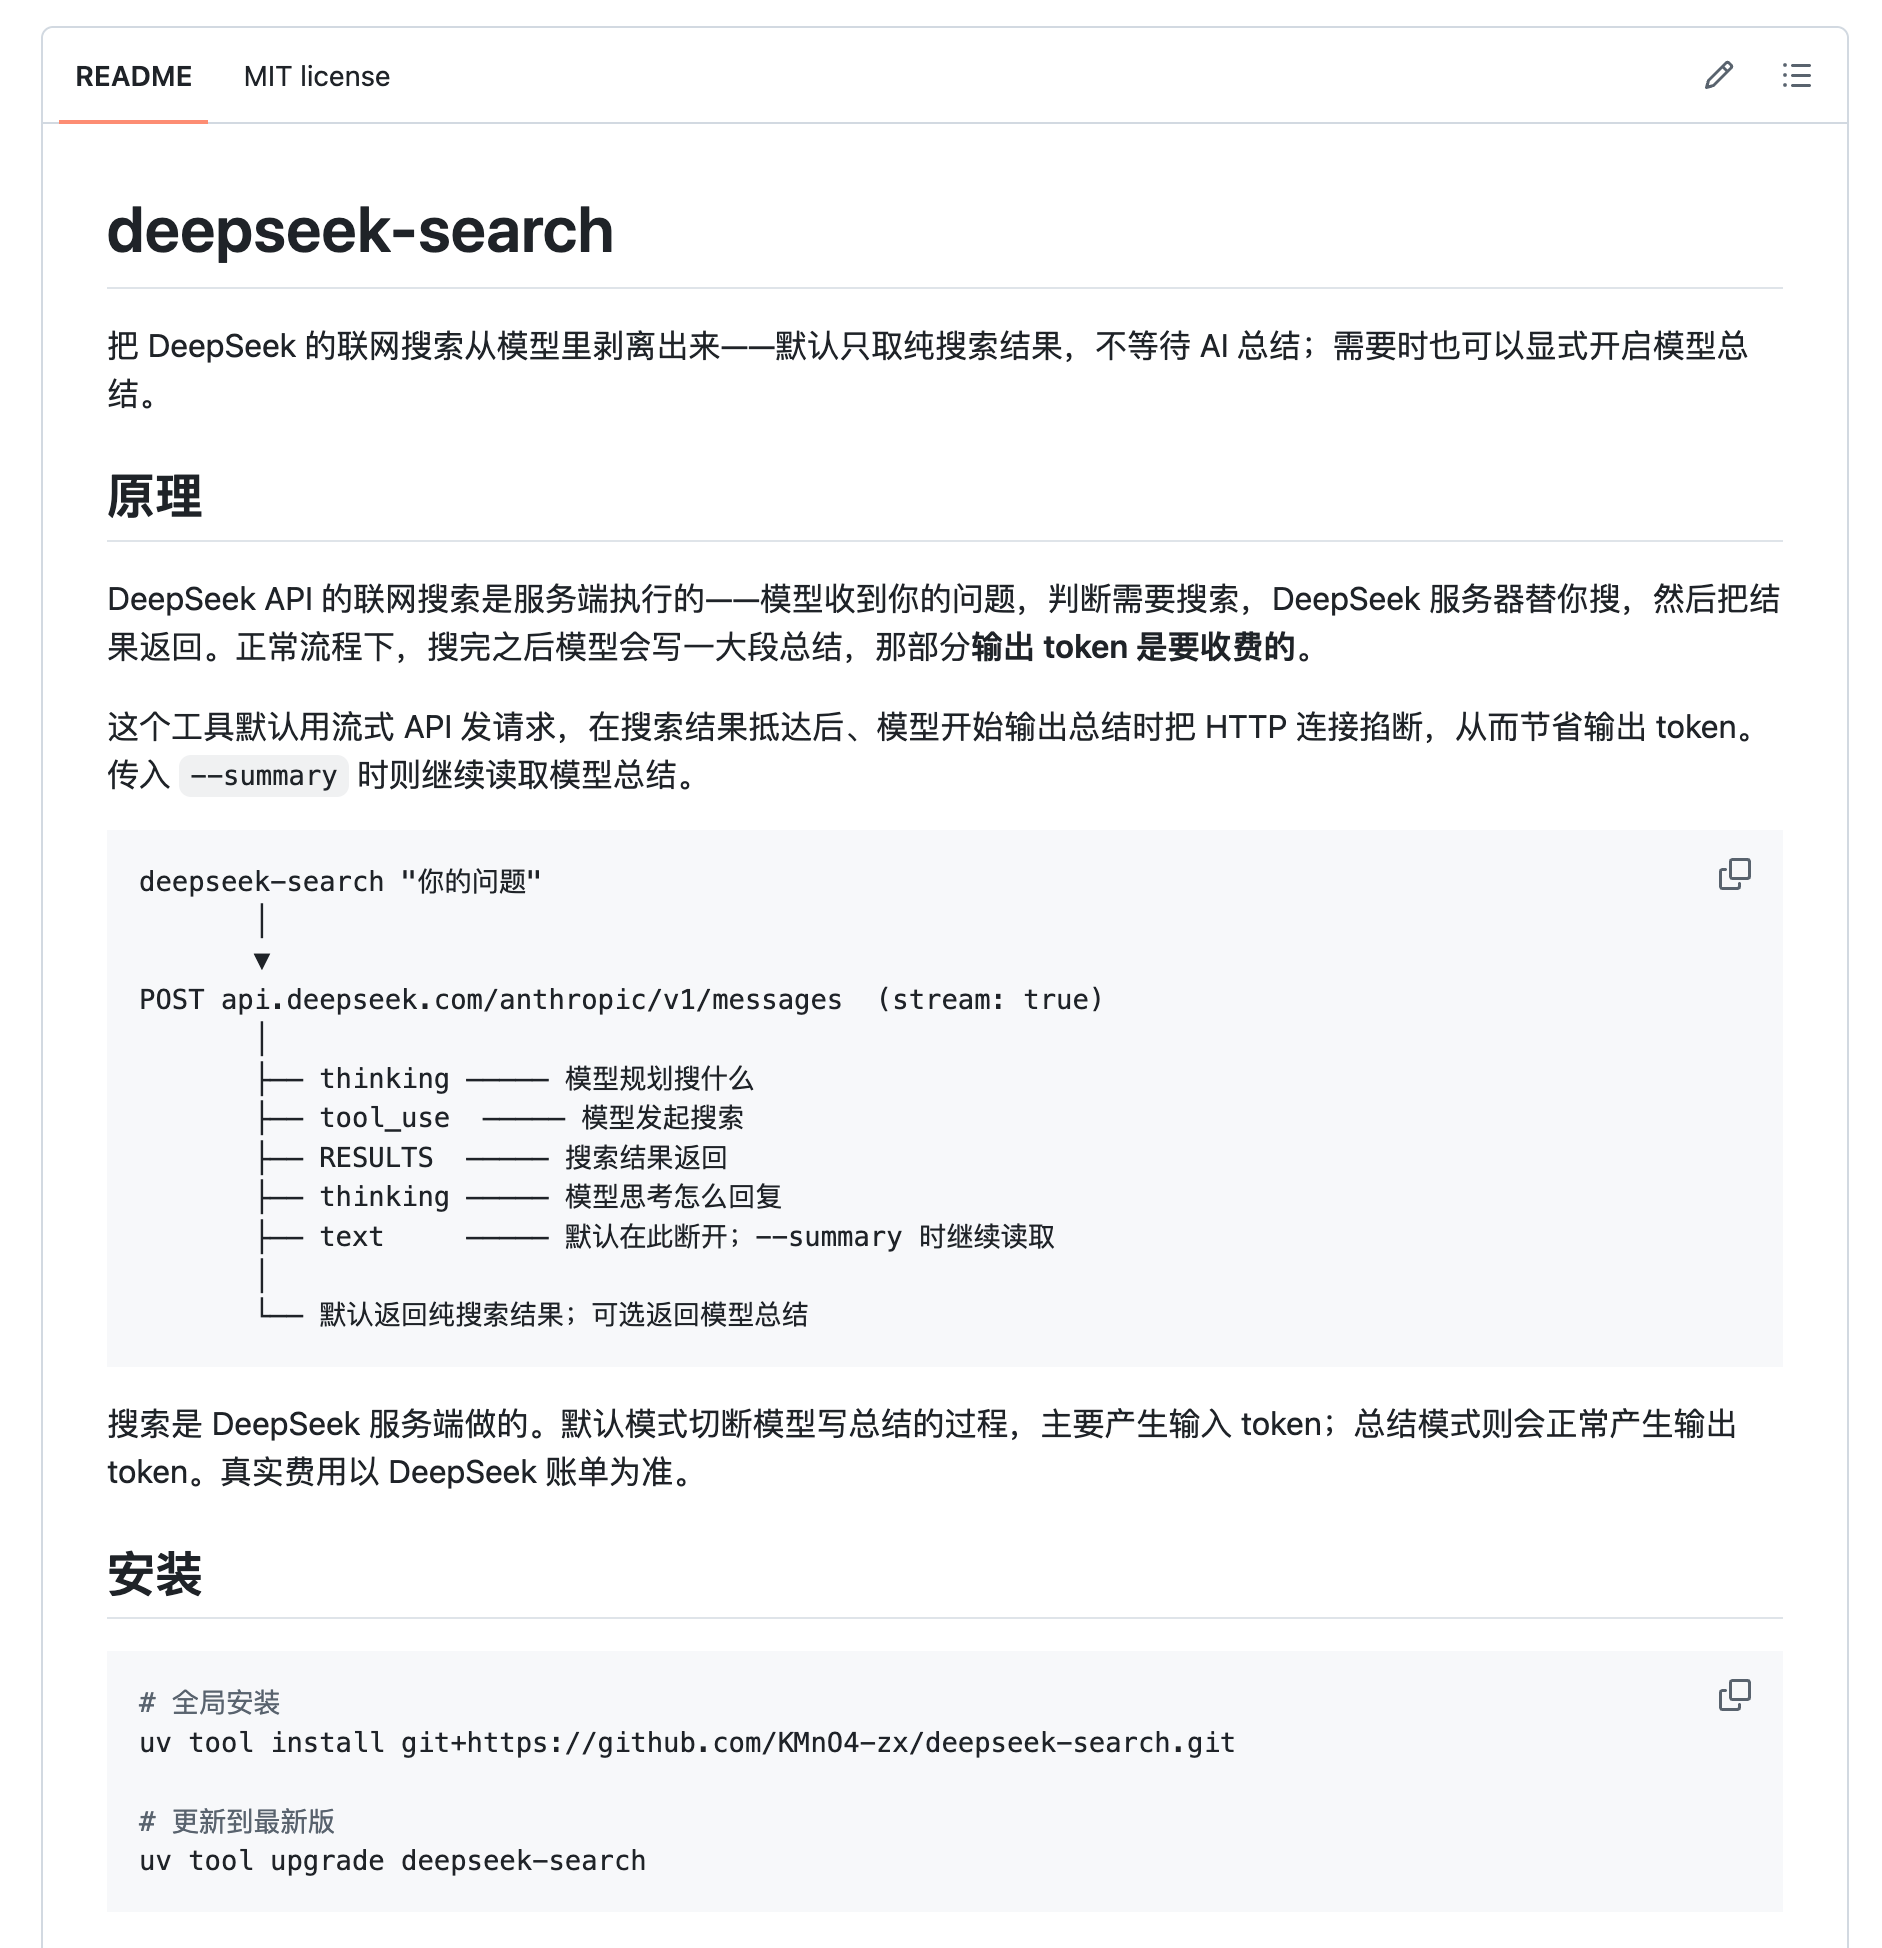
The following tool screenshot is retained as a historical record. For current commands, see the quick start.
Per-benchmark results are:
| Model / Checkpoint | Macro EM | Format | 2Wiki | Bamboogle | HotpotQA | MuSiQue | NQ | PopQA | TriviaQA |
|---|---|---|---|---|---|---|---|---|---|
| Qwen3.5-4B | 44.29% | 88.57% | 50% | 70% | 60% | 20% | 40% | 20% | 50% |
| RL Step 20 | 50.00% | 97.14% | 60% | 70% | 70% | 30% | 40% | 30% | 50% |
The changes over those 20 steps were:
Macro EM: 44.29% → 50.00%(+5.71 pp,70 题中净增 4 题)
Format:   88.57% → 97.14%(+8.57 pp)
Both evaluations had 100% search/success_rate, with search/error_rate, search/429_rate and search/timeout_rate all at 0. Search failures and exhausted quotas therefore did not confound that Base / Step 20 comparison.
The following screenshot preserves the legacy DeepSeek training curves. Its red and green lines come from different search environments and record historical reward changes. The current official Search API results are shown in the Base / Step 30 chart above.
The red line is the legacy DeepSeek 20-step run; the green line is an earlier search experiment.
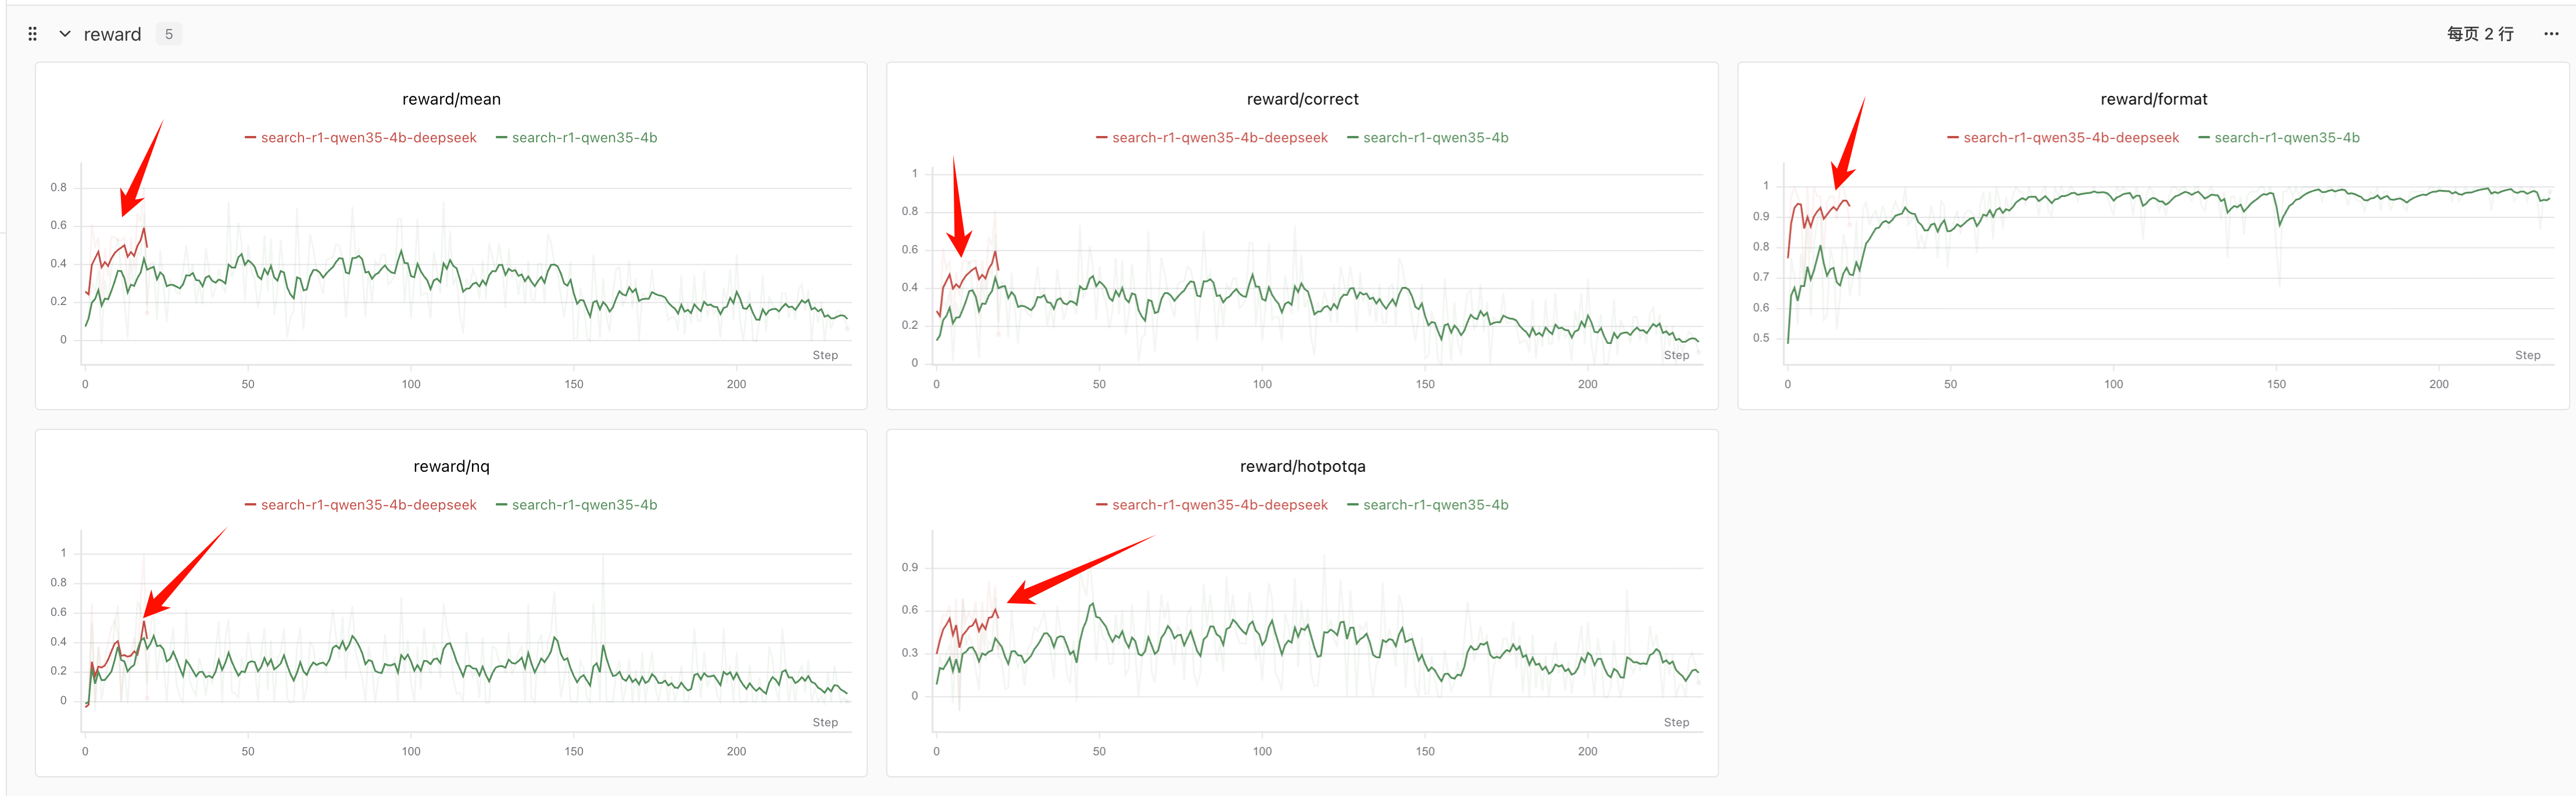
The 20-step results show an early optimization signal with stable search. They remain one run on 70 development questions, short of a larger evaluation with multiple random seeds.
The Search-R1 training loop in detail
The core idea is now established. Runnable code is in the GitHub repository.
The following sections follow an actual training step. The directory contains:
experiments/search-r1/
├── prepare_data.py   # 下载并整理训练与评测数据
├── data.py           # 读取本地 JSONL
├── protocol.py       # search tool schema、prompt 和 tool-call 解析
├── search.py         # DeepSeek 官方 API / Wikipedia 两种搜索后端
├── rollout.py        # 多轮工具调用状态机
├── reward.py         # EM + Format reward
├── train.py          # PyTRIO Search-R1 训练循环
├── eval.py           # Base / checkpoint 统一评测
└── analyse.py        # 绘制 DeepSeek checkpoint 结果图
Step 1: prepare questions and answers
Data comes from the official PeterJinGo/nq_hotpotqa_train, downloaded at a fixed version through a ModelScope mirror.
The preparation script is prepare_data.py.
Training data contains:
| Source | Questions |
|---|---|
| NQ | 79,168 |
| HotpotQA | 90,447 |
| Total | 169,615 |
Training requires four fields:
{
  "id": "...",
  "question": "...",
  "answers": ["..."],
  "data_source": "nq"
}
There are no annotated search queries or expert reasoning trajectories. The model receives a question, then generates its own search process under the current policy.
The distinction is:
We do not use SFT to imitate a fixed search path. Final outcomes provide rewards for exploring useful paths.
Step 2: declare search as a model tool
The protocol is in protocol.py.
The search schema is short:
SEARCH_TOOL = {
    "type": "function",
    "function": {
        "name": "search",
        "description": "Search the web for evidence. Use a concise English query.",
        "parameters": {
            "type": "object",
            "properties": {
                "query": {
                    "type": "string",
                    "description": "A concise English search query.",
                },
            },
            "required": ["query"],
        },
    },
}
Each turn injects tools through Qwen3.5's own chat template:
prompt_tokens = tokenizer.apply_chat_template(
    messages,
    tools=[SEARCH_TOOL],
    tokenize=True,
    add_generation_prompt=True,
    enable_thinking=False,
)
The model emits structured <tool_call> output, which protocol.py parses into a query. After real search, the result returns in a role="tool" observation; no guessed stop word is needed to infer search intent.
Search backends are implemented in search.py. Training and evaluation use the same client factory:
search_client = create_search_client(
    args.search_backend,
    Path(__file__).resolve().parent / ".env",
    count=args.search_count,
    timeout=args.search_timeout,
)
DeepSeekSearchClient sends Bearer-authenticated requests directly through httpx, mapping title, snippet, site_name and url to shared SearchItem records. WikipediaSearchClient obtains the top 3 English excerpts and URLs in one Action API call. Both return the same SearchResult. DeepSeek queries are limited to 128 Unicode characters; empty or overlong queries return an observable tool error so the model can revise them on the next turn.
Both clients log success, errors, 429 responses and latency. DeepSeek also records actual HTTP requests and successful requests that meet billing conditions, replacing the old search-model token metrics. Status codes 408, 429 and 5xx, along with network timeouts, receive bounded retries; authentication and balance errors return directly as tool errors. Results normally enter the token budget as complete items. If the first item is too long, only its body is shortened, preserving its title and source instead of discarding the entire search.
Step 3: let trajectories diverge after search
This is an easily missed detail of multi-turn implementation.
The first 8 trajectories for a question share an identical prompt, so one request can sample them together:
sample_async(
    prompt=shared_prompt,
    num_samples=8,
)
After that, they may produce 8 different queries and receive 8 different observations:
query_i 不同
→ observation_i 不同
→ 下一轮 prompt_tokens_i 不同
One shared prompt with num_samples=8 no longer represents those branches. Each trajectory must advance independently through concurrent num_samples=1 requests.
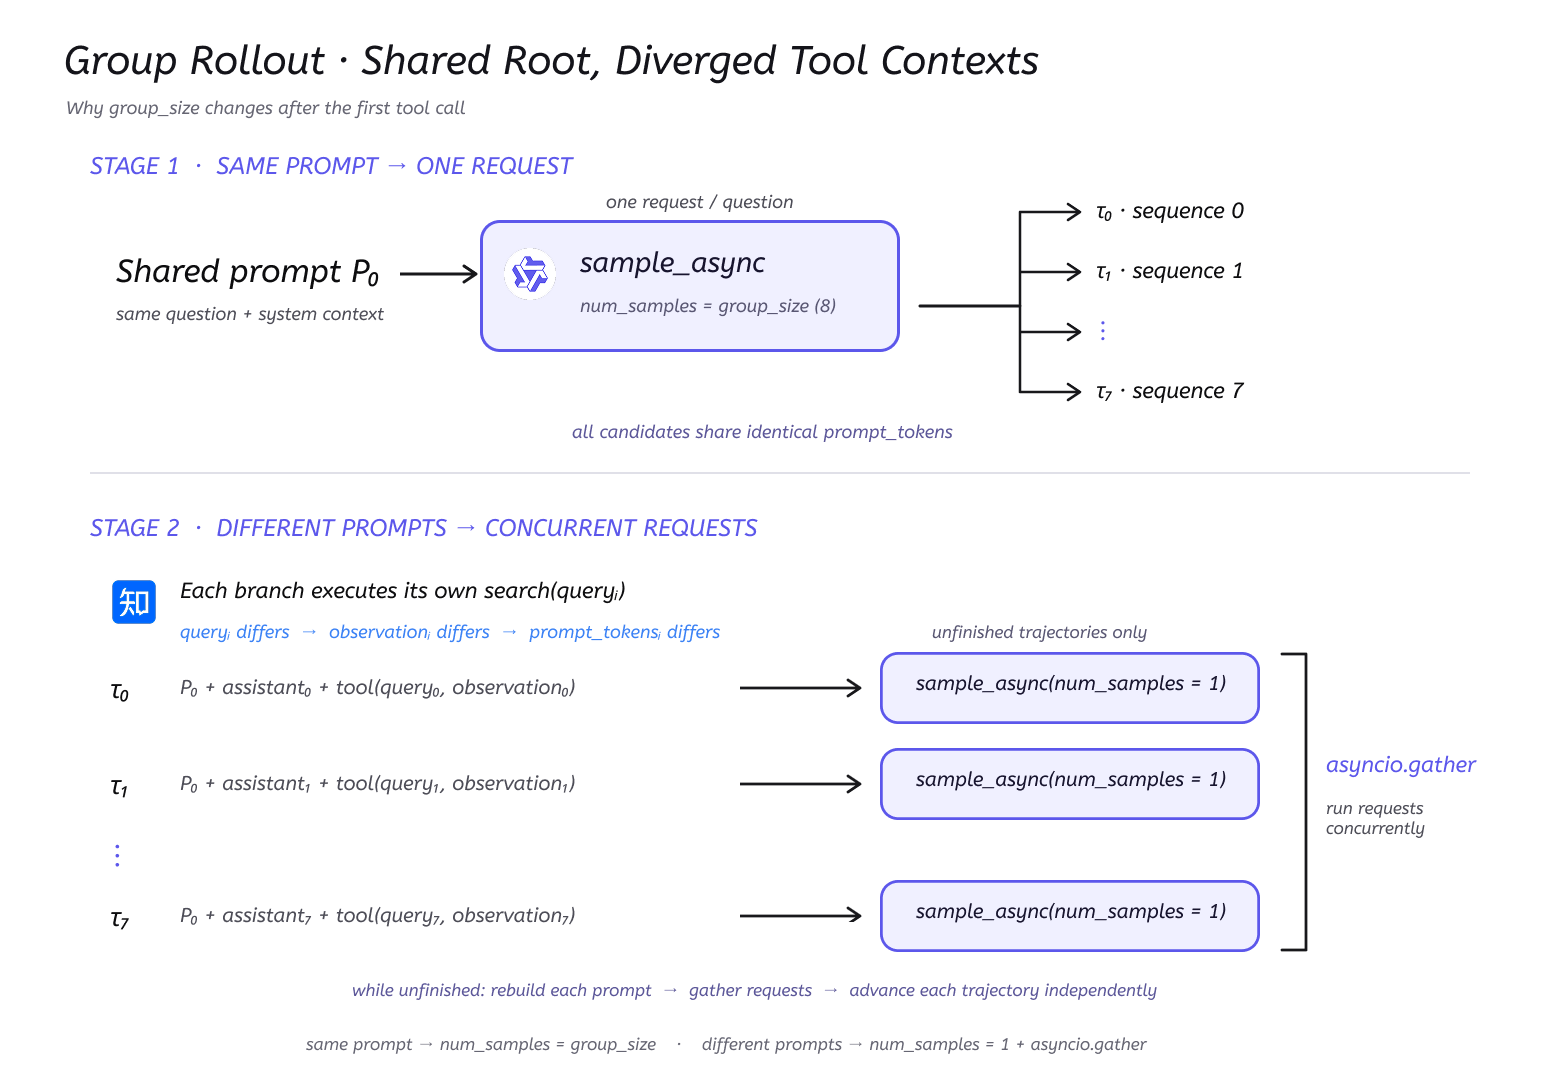
The state machine is in rollout.py:
第一轮:
每道题 1 个 shared prompt × num_samples=8

第一次搜索之后:
每条未结束轨迹 1 个独立 prompt × num_samples=1
多个 sample_async 用 asyncio.gather 并发
Within one trajectory, actions remain strictly sequential:
assistant generation
→ search(query)
→ tool observation
→ next assistant generation
Concurrency applies across trajectories. This preserves causality without forcing all 64 trajectories to wait serially.
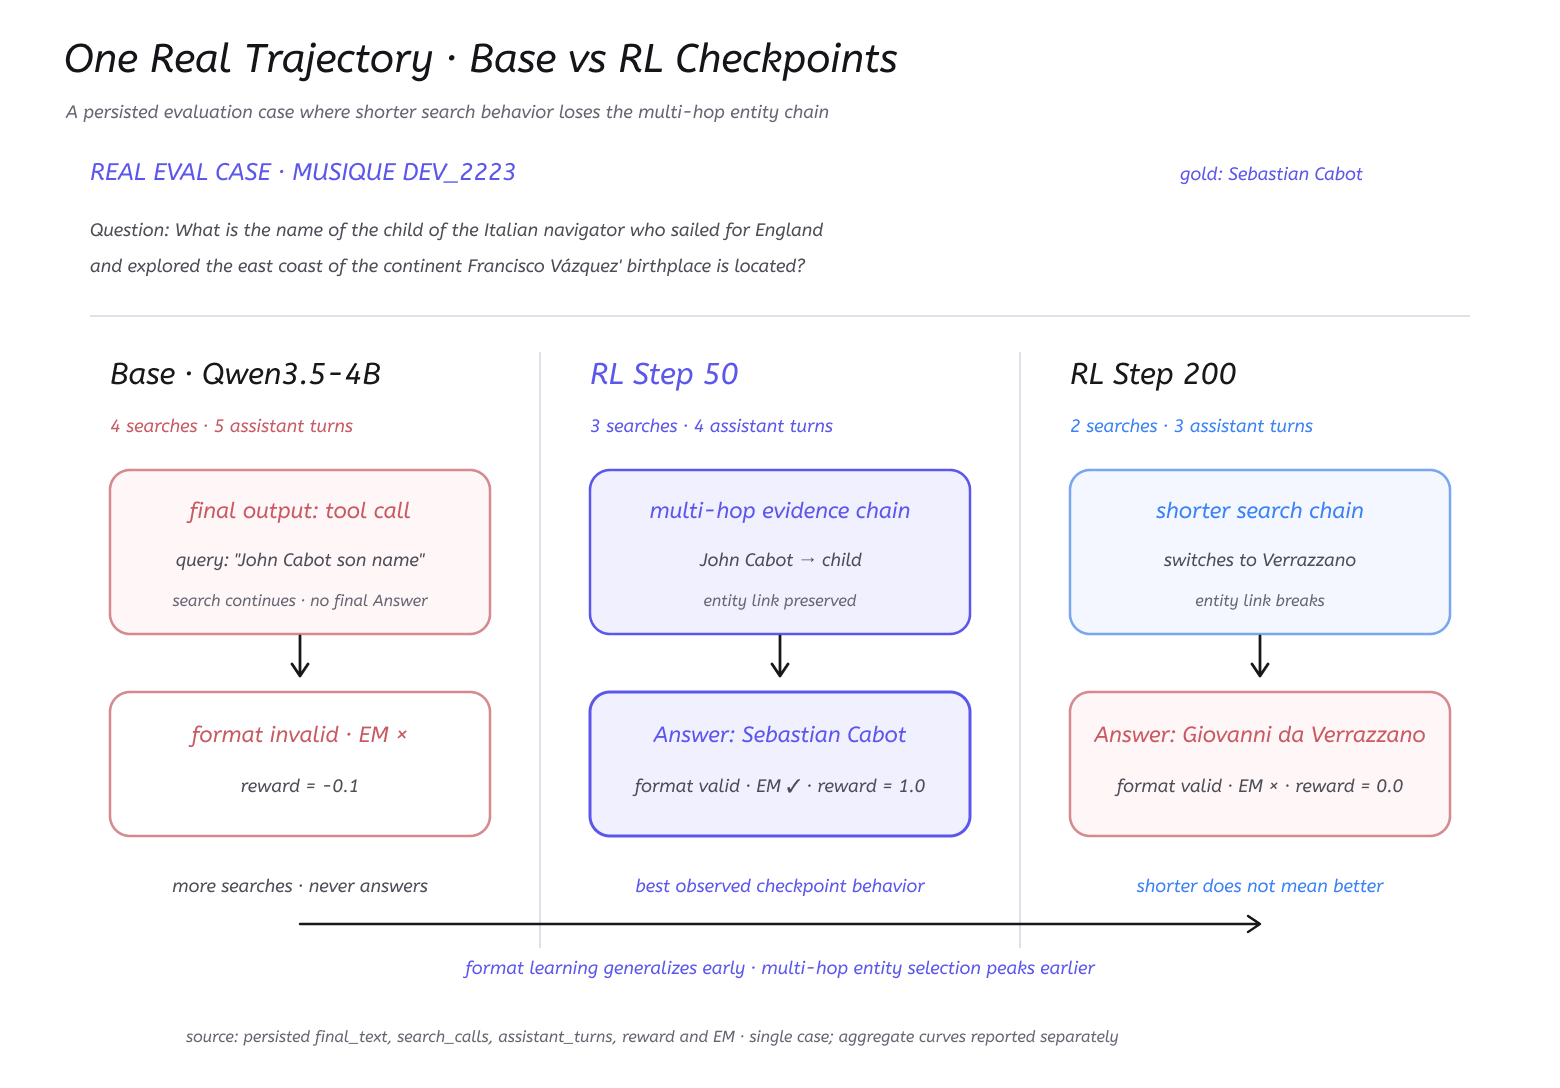
The following figure preserves an early MuSiQue evaluation trajectory, showing search and answer behavior for the same question at Base, Step 50 and Step 200. It helps inspect whether the entity chain survives and when search stops. A single historical example should be considered separately from the aggregate evaluation for its run.
Step 4: calculate reward from the final answer
Reward is implemented in reward.py.
The model must leave exactly one nonempty final answer:
Answer: <short answer>Three reward values are used:
| Final result | Reward |
|---|---|
| Valid format and correct answer | 1.0 |
| Valid format and incorrect answer | 0.0 |
| Invalid format or missing answer | -0.1 |
The code is only a few lines:
def score_answer(text: str, references: list[str]) -> RewardResult:
    answer = extract_answer(text)
    if answer is None:
        return RewardResult(-0.1, False, False, None)
    exact_match = any(
        normalize_answer(answer) == normalize_answer(reference)
        for reference in references
    )
    return RewardResult(float(exact_match), True, exact_match, answer)
There is no separate reward for search count or manually scored intermediate queries.
Such rewards could encourage endless searches or superficial keyword matching. This implementation uses final outcomes and lets the policy explore useful intermediate searches.
Step 5: calculate advantages within each question
The 8 trajectories produce 8 final rewards. Calculate:
See rollout.py:
mean_reward = sum(item.reward for item in group) / len(group)
for item in group:
    item.advantage = item.reward - mean_reward
For example, a group may have these rewards:
[1.0, 0.0, 0.0, -0.1, 1.0, 0.0, 0.0, -0.1]Its mean is 0.225, producing these three kinds of advantage:
1.0  → +0.775
0.0  → -0.225
-0.1 → -0.325
Relatively better trajectories become more likely, and worse ones less likely, within the same question.
If all rewards within a group match, every advantage is 0 and that group contributes no policy gradient. If the entire rollout batch has zero advantages, the code skips the parameter update. Search failures can therefore consume an expensive rollout without providing a useful relative gradient.
Step 6: keep search results in context and mask their loss
This is a central difference from single-turn GRPO.
A multi-turn trajectory contains four kinds of token:
system + user
assistant search(query)
tool observation
assistant final Answer
Assistant-generated tokens are actions to optimize. Search observations are environment state: they must remain visible but must not be trained as generated actions.
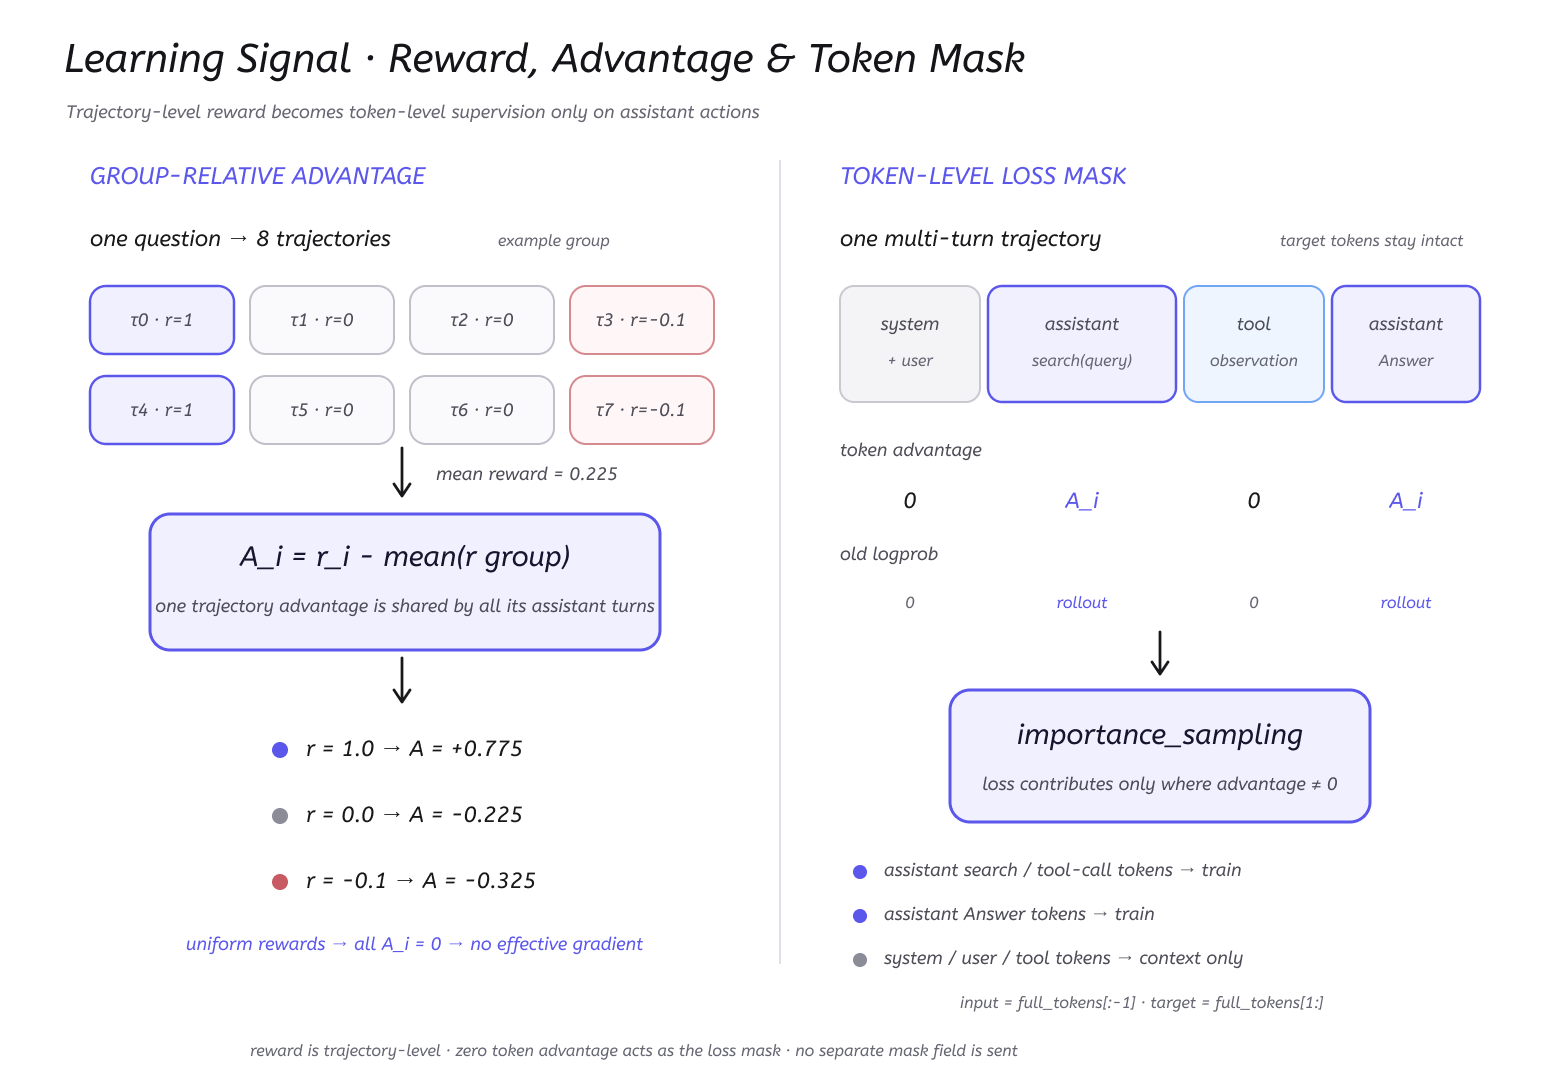
No extra mask field is required here. Observation tokens receive zero advantage and zero old-logprob placeholders:
system / user / tool observation: advantage = 0
assistant tool call / final answer: advantage = trajectory_advantage
See build_datum() in train.py.
The core logic is:
full_tokens += delta_observation + turn.completion_tokens
old_logprobs_by_token += [0.0] * len(delta_observation) + turn.logprobs
advantages_by_token += (
    [0.0] * len(delta_observation)
    + [trajectory.advantage] * len(turn.completion_tokens)
)

input_tokens = full_tokens[:-1]
target_tokens = full_tokens[1:]
old_logprobs = old_logprobs_by_token[1:]
advantages = advantages_by_token[1:]
Then construct the PyTRIO Datum:
datum = trio.Datum(
    model_input=trio.ModelInput.from_ints(input_tokens),
    loss_fn_inputs={
        "target_tokens": np.asarray(target_tokens, dtype=np.int64),
        "logprobs": np.asarray(old_logprobs, dtype=np.float32),
        "advantages": np.asarray(advantages, dtype=np.float32),
    },
)input_tokens, target_tokens, logprobs and advantages must share consistent autoregressive alignment and equal lengths. Old log probabilities come from the rollout sampler and cannot be recomputed after a model update.
Search observations can then influence later decisions without incorrectly entering the policy loss as model actions.
Step 7: update the policy using complete trajectories
By default, each training step contains:
8 questions × 8 trajectories = 64 trajectoriesCalculate rewards and advantages over each question's full group, build a trio.Datum for every trajectory, and submit them together to forward_backward:
datums = [build_datum(trajectory) for trajectory in trajectories]
if any(trajectory.advantage != 0.0 for trajectory in trajectories):
    result = training_client.forward_backward(
        datums,
        loss_fn="importance_sampling",
    ).result()
    training_client.optim_step(adam_params).result()
PyTRIO 0.2.9 supports automatic gradient accumulation. The SDK splits physical requests according to server limits, normalizes over the complete logical batch, accumulates gradients and returns aggregated training metrics. This project retains only the 8,192-token limit for each training Datum and uses the SDK's returned loss_mean directly.
Zero-advantage trajectories remain in the full batch so the SDK normalizes using the complete rollout denominator. A batch with no training signal skips the update. Each effective training step makes one forward_backward call and one optim_step call.
See build_datum() and the training loop in train.py.
Running a 20-step experiment
The following path runs the full Search-R1 pipeline with a small training budget, without a separate simplified algorithm branch.
1. Install and log in
git clone https://github.com/datawhalechina/agentic-rl-lab.git
cd agentic-rl-lab

uv sync
trio login
swanlab login
PyTRIO handles training and sampling remotely; the local host needs a CPU environment.
2. Download and prepare data
uv run python experiments/search-r1/prepare_data.pyThis generates:
experiments/search-r1/datasets/
├── train.jsonl    # 169,615 道训练题
├── dev.jsonl      # 固定 70 道评测题
└── test.jsonl     # 完整评测池
3. Select and configure search
Copy the environment template:
cp experiments/search-r1/.env.example experiments/search-r1/.envThe default backend is the official DeepSeek Search API. Set the key in experiments/search-r1/.env:
DEEPSEEK_API_KEY=your_deepseek_api_keyDEEPSEEK_KEY is also supported. Existing process environment variables take precedence over values with the same name in the file. No installation or login for the legacy deepseek-search tool is required.
For key-free public search, use --search-backend wikipedia. It searches English Wikipedia, defaults to concurrency 3 and timeout 15 seconds, and needs no .env change.
Check search/success_rate before full training.
4. Run a small 20-step experiment
Enter the Search-R1 directory:
cd experiments/search-r1With DeepSeek Search:
uv run python train.py \
    --max-steps 20 \
    --questions-per-batch 8 \
    --group-size 8 \
    --save-every 5 \
    --base-model Qwen/Qwen3.5-4B \
    --search-backend deepseek \
    --run-name search-r1-qwen35-4b-deepseek \
    --swanlab-mode online
With Wikipedia:
uv run python train.py \
    --max-steps 20 \
    --questions-per-batch 8 \
    --group-size 8 \
    --save-every 5 \
    --base-model Qwen/Qwen3.5-4B \
    --search-backend wikipedia \
    --run-name search-r1-qwen35-4b-wikipedia \
    --swanlab-mode online
Default search concurrency / timeout are 16 / 60 seconds for DeepSeek and 3 / 15 for Wikipedia. Override them with --search-concurrency and --search-timeout. DeepSeek's --search-count defaults to 3 and accepts 1–50. For a longer run, set --max-steps 100 and --save-every 50.
Each step uses 8 questions and 8 real multi-turn trajectories per question. Every 5 steps it saves:
*-state    # 用于断点续训
*-weights  # 用于采样与评测
Over 20 steps, inspect:
- Whether
reward/formatrises. - Whether final
Answer:outputs become reliable. - Early changes in
reward/correct. - Search counts and assistant turns.
- Stability of
search/success_rate. - The frequency of degenerate groups.
5. Evaluate Base and Step 20
Using DeepSeek Search as the example, evaluate Base first:
uv run python eval.py \
    --batch-size 16 \
    --base-model Qwen/Qwen3.5-4B \
    --search-backend deepseek \
    --search-count 3 \
    --search-concurrency 16 \
    --search-timeout 60 \
    --output eval_result/eval_results_base_deepseek_api.jsonl
Training prints the Step 20 sampler weights path. Pass it to the evaluator:
uv run python eval.py \
    --batch-size 16 \
    --model-path 'trio://YOUR_STEP_20_SAMPLER_WEIGHTS' \
    --search-backend deepseek \
    --search-count 3 \
    --search-concurrency 16 \
    --search-timeout 60 \
    --output eval_result/eval_results_rl_step_20_deepseek_api.jsonl
For Wikipedia, use --search-backend wikipedia --search-concurrency 3 --search-timeout 15 in both evaluations. Give different backends different output filenames. Base and checkpoint must share the backend, excerpt field and search settings. The legacy Evidence integration and official Search API are different environments, so their absolute scores should not be directly mixed.
For an initial pipeline check, add --limit 20 before running the fixed 70-question evaluation.
eval.py uses the same tokenizer, tool protocol, search environment, trajectory limits and EM rules for Base and checkpoint.
6. Plot evaluation results
Plot the current official DeepSeek Search API Base / Step 30 comparison:
uv run python analyse.py --preset deepseek-apiThis preset reads eval_result/eval_results_base.jsonl and eval_result/eval_results_rl_step_30.jsonl, then writes images/deepseek_api_base_vs_step30.png.
Plot the historical DeepSeek Evidence Base / Step 20 comparison:
uv run python analyse.py --preset deepseekanalyse.py reads each JSONL's final summary.metrics and checks the fixed 70 questions, matching search API or model, excerpt field and search settings before combining results.
Which training metrics matter?
One reward curve is insufficient for Search-R1.
| Metric | Question |
|---|---|
reward/mean | How are complete trajectories performing on average? |
reward/correct | Is final-answer accuracy changing? |
reward/format | Does the model stop searching and answer in the required format? |
rollout/search_calls | How often does each trajectory search? |
rollout/turns | Are trajectories becoming longer or shorter? |
rollout/degenerate_group_rate | How many questions lack relative learning signals? |
train/loss_tokens_per_rollout_batch | How many assistant tokens enter the loss? |
search/success_rate | Is the tool environment reliable? |
search/error_rate | Might external errors contaminate rewards? |
search/latency | Is search a rollout bottleneck? |
search/results | How much evidence is returned per search? |
search/api_requests / search/billable_requests | How many HTTP requests does each tool call send, and how many meet the billing conditions? |
If correctness falls while search errors rise, inspect the environment before attributing the change to the policy.
Unlike a typically deterministic mathematical verifier, a tool environment can time out, rate-limit, return nothing or change over time. Environment quality is itself an experimental variable.
Reproduction boundaries
First, this reproduces the core Search-R1 algorithm, with different model, backend, framework and some settings. Its absolute scores cannot be directly compared with the paper.
Second, 70 fixed questions, 10 per benchmark, are useful for checking behavior and implementation. They do not replace larger multi-seed experiments.
Third, the current official Search API Base / Step 30 evaluations use identical search settings and both have 100% search success. The observed gains are +2.86 pp Macro EM and +8.57 pp Format, while one run is insufficient to establish stable generalization.
Fourth, DeepSeek Search and Wikipedia cover different evidence. The legacy Evidence integration and official Search API also provide different search environments. Checkpoints are compared only within their respective environments.
Within those limits, the experiment provides a runnable way to understand Search-R1 with modest local storage and compute requirements.
Summary
Search-R1's central loop can be expressed simply:
1. 给模型一个问题和搜索工具。
2. 让当前策略生成多轮 search / observation / answer 轨迹。
3. 只根据最终答案计算 reward。
4. 在同一道题的多条轨迹之间计算相对 advantage。
5. 只训练模型生成的 assistant action token。
6. 用 PyTRIO importance_sampling 更新 LoRA。
7. 导出新 sampler,继续下一轮 rollout。
It trains the ability to actively obtain useful information from an environment.
The original retrieval setup's roughly 160 GB database and 180 GB memory requirement are relevant to a close reproduction. For learning the algorithm, switchable online search makes the entry point much lighter.
The current 30-step run shows changes in Format rate and search behavior, along with higher EM on the fixed 70 questions. Wikipedia offers a key-free backend, while the official DeepSeek Search API offers broader web coverage and higher concurrency.
The appeal for me is spending time on rewards, rollouts, masks and experiment design instead of first maintaining a large training/inference cluster.
I expect model training to become more like using cloud storage or a database: ordinary Python describes the algorithm, while sampling, training and checkpoints are remote capabilities. That could make more experiments practical for individual researchers and small teams.
I had not yet chosen the next chapter when writing this note—perhaps GSPO, OPSD, or another Agentic RL idea.
References
Paper and official implementation
- Bowen Jin et al. Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning, 2025.
- Bowen Jin et al. An Empirical Study on Reinforcement Learning for Reasoning-Search Interleaved LLM Agents, 2025.
- PeterGriffinJin/Search-R1